Hey there! As a Pipeline Filter supplier, I'm super stoked to share with you how to use the Pipeline Filter pattern for data caching. It's a pretty nifty concept that can really level up your data management game.
First off, let's break down what the Pipeline Filter pattern is all about. Picture a pipeline, like an actual pipe system. In the data world, this pipeline is a series of steps or filters that data passes through. Each filter has a specific job, kind of like workers on an assembly line. They take in data, do something to it, and then pass it along to the next filter.
Now, why is this pattern so great for data caching? Well, caching is all about storing data so you can access it quickly later. With the Pipeline Filter pattern, you can set up filters to pre - process the data before it gets cached. This means you can transform, clean, or enrich the data in a way that makes it more useful and easier to retrieve.
Let's start with the basics of setting up a Pipeline Filter for data caching. The first step is to define your filters. You might have a filter that validates the data. For example, if you're dealing with user profiles, this filter could check if all the required fields are filled in. Another filter could format the data. Maybe you want all dates to be in a specific format before caching.
# A simple example of a validation filter in Python
def validation_filter(data):
    if 'name' in data and 'age' in data:
        return data
    return None


# A formatting filter
def formatting_filter(data):
    if 'date_joined' in data:
        data['date_joined'] = data['date_joined'].strftime('%Y-%m-%d')
    return data
Once you've defined your filters, you need to connect them in a pipeline. You can do this by chaining the functions together.
def pipeline(data):
    data = validation_filter(data)
    if data:
        data = formatting_filter(data)
    return data
When it comes to caching, you can use a simple in - memory cache like Python's functools.lru_cache for small - scale applications.
import functools


@functools.lru_cache(maxsize=128)
def cached_pipeline(data):
    return pipeline(data)
Now, let's talk about the benefits of using the Pipeline Filter pattern for data caching. One major advantage is modularity. Each filter is a self - contained unit. This means you can easily add, remove, or modify filters without affecting the whole system. If you later decide you need a new filter to encrypt the data before caching, you can just plug it into the pipeline.
Another benefit is scalability. As your application grows and the amount of data increases, you can scale your pipeline by adding more filters or optimizing existing ones. You can also distribute the filters across multiple servers if needed.
Let's take a look at some real - world scenarios where the Pipeline Filter pattern for data caching shines. Suppose you're running an e - commerce website. You have a lot of product data that needs to be cached. You can set up a pipeline with filters to:
- Validate the product information (check if the price is within a reasonable range, if the description is not empty).
- Format the data (make sure all product names are in title case).
- Enrich the data (add additional information like related products).
By doing this, you ensure that the cached data is accurate, consistent, and useful.
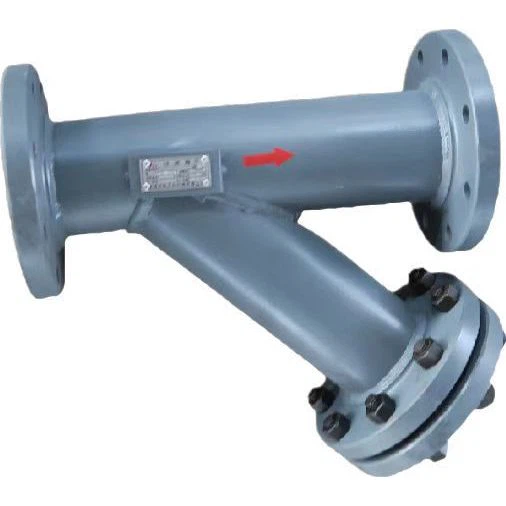
Now, I want to mention some of the products we offer as a Pipeline Filter supplier. We have high - quality Pipeline Filter that can be used in various industrial and data - related applications. Our filters are designed to be durable and efficient, ensuring that your data pipeline runs smoothly.
We also offer Sight Glass which can be used to monitor the flow of data in your pipeline. It's like having a window into your data system, allowing you to quickly spot any issues or bottlenecks.
And for those of you who need to secure your pipelines, our U-Type Bolt is a great option. It provides a strong and reliable way to hold your pipeline components in place.
If you're interested in implementing the Pipeline Filter pattern for data caching in your business, we're here to help. Whether you need advice on setting up the pipeline, choosing the right filters, or purchasing our products, we've got you covered.
In conclusion, the Pipeline Filter pattern is a powerful tool for data caching. It offers modularity, scalability, and the ability to pre - process data in a flexible way. By using our high - quality Pipeline Filter products, you can take your data management to the next level.
If you're thinking about implementing this pattern in your organization or have any questions about our products, don't hesitate to reach out. We're always happy to have a chat and discuss how we can work together to meet your data caching needs.

References:
- Design Patterns: Elements of Reusable Object - Oriented Software by Erich Gamma, Richard Helm, Ralph Johnson, and John Vlissides
- Python Data Science Handbook by Jake VanderPlas